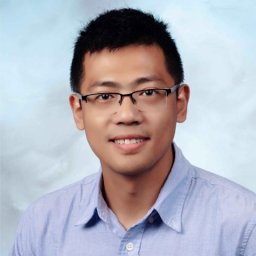
I am a Senior Staff Research Scientist and Research Lead at Salesforce AI Research. I study how to build trustworthy and self-improving AI agents, with a focus on safety, alignment, and reliability. My work combines agentic post-training, behavioral evaluation, and model–harness co-evolution to connect honesty, calibration, and uncertainty with learning and control in coding, tool-using, and long-horizon agents.
I am interested in the gap between what an agent knows, what it does, and when it should stop or ask for help. Addressing this gap requires more than a stronger model: training signals, evaluation protocols, the execution harness, and the environment all shape agent behavior.
Previously, I was a Senior Staff Research Scientist and founding research lead at Intuit AI Research, where I built LLM reliability and evaluation infrastructure used by 1,600+ internal users, and automated prompt optimization pipelines used by 2,000+ developers. This work was recognized with the Intuit CTO Award (top 1%). Earlier, at Oak Ridge National Laboratory, I worked on distributed deep learning at 20,000+ GPUs on Summit and served as PI/co-PI on seven DOE/ORNL projects ($6.4M total) in AI for Science. I received the DOE Promising Early-Career Researcher Award and earned my Ph.D. at Johns Hopkins University.
Research Directions
Research Writing
All articlesLong-form notes connecting recent research, practical agent design, and open questions.
Alignment & safety
Alignment After Agency: Safety for Models That Act
Agent behavior, oversight, and safeguards across the model, harness, and environment.
Calibration & decision models
Jev: When Calibration Becomes an API
A living review of calibrated decision models, RLCD, open tooling, and their limits.
Agent reliability
Calibrating Long-Horizon Agents
Measuring trajectory uncertainty—and using it to reflect, abstain, ask, and route.
Agentic post-training
Environment Scaling for Agentic RL
How tasks, environments, and verifiers become scalable reinforcement-learning signals.
News & Updates
| 09/2026 | Prospective Hindsight: Self-Calibrating Reinforcement Learning via Prediction–Reality Gaps has been accepted to NeurIPS 2026. |
|---|---|
| 08/2026 | Agentic Uncertainty Quantification and Seeing is Believing? Evaluating Vision-Language Model Susceptibility in Agent-to-Agent Multimodal Persuasion have been accepted to EMNLP 2026. |
| 05/2026 | 2 papers accepted by ICML 2026: Agentic Confidence Calibration and LaTtE-Flow. |
| 04/2026 | Presenting our NuRL paper (code) at ICLR 2026 in Brazil! 🇧🇷 |
| 04/2026 | We release CaOPD — calibration-aware on-policy distillation! Read the paper, check out the code and Hugging Face. |
| 04/2026 | 2 papers accepted by ACL 2026: From Passive Metric to Active Signal and Don’t Stop Early: Scalable Enterprise Deep Research. |
| 02/2026 | 2 invited talks on Building Reliable Long-horizon Agents at UCSD EnCORE Workshop and EPFL. |
| 01/2026 | 1 paper accepted by ICLR 2026: Nudging the Boundaries of LLM Reasoning. |
| 12/2025 | Attending NeurIPS 2025 in San Diego! 🇺🇸 |
| 10/2025 | We published a blog on Towards Trustworthy Enterprise Deep Research at Salesforce. |
Selected Publications
For the full publication list, see Google Scholar.
01 Safety, Alignment & Agent Reliability
Behavioral alignment, honesty, uncertainty, calibration, and reliable decision-making—from LLMs to agent trajectories.
- ICML 2026In International Conference on Machine Learning, 2026
Process-level signals for estimating whether an agent trajectory will succeed.
- EMNLP 2026In Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026
Turning uncertainty into active memory and reflection controls for agents.
- ACL 2026In Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics, 2026
A survey of uncertainty as a control and training signal, rather than only a diagnostic metric.
- EMNLP 2026In Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing, 2026
Evaluating behavioral susceptibility to agent-to-agent multimodal persuasion.
- Under reviewAgentic Self-Awareness: Aligning Knowing, Acting, and Holding2026Submitted to ICLR 2027.
Testing the gap between recognizing blocked tasks and actually withholding unauthorized or infeasible actions.
- EMNLP 2025In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025
Statistical approaches to factuality guarantees for vision-language models.
- NAACL 2025In Proceedings of the 2025 Conference of the North American Chapter of the Association for Computational Linguistics, 2025
Inference-time attention editing to mitigate contextual hallucinations.
- AISTATS 2024In International Conference on Artificial Intelligence and Statistics, 2024
Earlier UQ foundations: distance-aware representations for deterministic uncertainty estimation.
- EMNLP 2023In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, 2023
Black-box hallucination detection through semantic-aware cross-check consistency.
- CVPR 2022In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2022
Earlier privacy foundations: auditing federated-learning defenses through gradient leakage.
02 Agentic Post-training & Reinforcement Learning
Reinforcement learning, on-policy distillation, experience-based supervision, and cost-effective adaptation of language models.
- NeurIPS 2026In Advances in Neural Information Processing Systems, 2026Accepted September 24, 2026.
Self-calibrating reinforcement learning using the gap between predicted and observed outcomes.
- arXiv 20262026Under review at ICLR 2027.
Separating capability gains from confidence calibration in on-policy distillation.
- ICLR 2026In International Conference on Learning Representations, 2026
Hint-guided exploration to help reinforcement learning move beyond all-failure rollouts.
- Under reviewSelf-Retrospection Distillation: Turning Post-hoc Experiences into Prior Foresight2026Submitted to ICLR 2027.
Distilling post-hoc experience into prior foresight, without requiring the privileged experience at inference time.
- Under reviewFork Where the Model Changes Its Mind: Belief-Shift Branching for Tree-Structured Reinforcement Learning2026Submitted to ICLR 2027.
Allocating tree-structured exploration to points where the model’s answer belief changes.
- Under reviewLessons from Agentic Post-Training of MLLMs for Multimodal Web Search2026Submitted to ICLR 2027.
Studying how rollout design, tools, summarizers, and judges affect agentic post-training and evaluation.
- EMNLP 2025In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: Industry Track, 2025
Confidence-aware control of self-guided reasoning trajectories.
- EMNLP 2024In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 2024
Synthesizing structured knowledge for injection through continual pre-training, SFT, and retrieval.
- NeurIPS 2023In Advances in Neural Information Processing Systems, 2023
Cost-effective language-model adaptation through sparse human supervision and multi-fidelity feedback.
03 Self-Improving Agents & Model–Harness Co-Evolution
Joint improvement of models, harnesses, and training data, alongside earlier work on automated prompt optimization.
- Under reviewMDS-Zero: Self-Improving Multimodal Deep Search via Online QA–Solver Co-training2026Submitted to ICLR 2027.
Co-training a question generator and search solver with a fixed verification harness and seeded training data.
- Under review2026Submitted to ICLR 2027.
Examining how randomness, task order, and underspecified memory updates undermine reproducible self-improvement.
- Under reviewCoTrace: Data Recipes for Training Terminal Agents with Harness–Model Co-Evolution2026Submitted to ICLR 2027.
Routing failures into harness changes, runtime-matched training traces, and fresh online RL rollouts.
- ACL 2025In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics, 2025
Earlier prompt-level optimization: balancing strategic exploration and exploitation.
- ACL 2025In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics, 2025
A survey of heuristic-search methods for automated prompt optimization.
- EMNLP 2024OralIn Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track, 2024
Decomposed consistency evaluation coupled with explanation-guided response improvement.
- EMNLP 2024In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing - Industry Track, 2024
Jointly optimizing prompt performance and security rather than performance alone.
04 Agent & Multimodal Systems
Long-horizon search, retrieval, memory, multimodal understanding and generation, and system evaluation and efficiency.
- ACL 2026In Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics: Industry Track, 2026
Dependency-controlled information flow and evidence-aware stopping for enterprise deep research.
- ICML 2026In International Conference on Machine Learning, 2026
Unifying image understanding and generation with layerwise timestep experts for efficient flow-based sampling.
- Under reviewSpeculate with Memory: Lossless Acceleration for LLM Agents2026Submitted to ICLR 2027.
Using memory to improve a speculative executor, with exact-match acceptance and read-only tool constraints.
- EMNLP 2025OralIn Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025
A benchmark for reasoning-driven text-to-image generation.
- ICLR 2025In International Conference on Learning Representations, 2025
Modality-specialized adaptation layers and interleaved instruction data for joint text-and-image understanding and generation.
- EMNLP 2024OralIn Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 2024
Testing whether a retrieval corpus can actually support a query or query distribution.
- EMNLP 2024In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 2024
Efficient retrieval-context ranking with hypothetical query embeddings.
Recent Talks
→ all talks
- Feb 27, 2026Invited TalkReliable Long-horizon Agents
- Feb 17, 2026Invited TalkReliable Long-horizon AgentsEPFL
Awards & Honors
- • Intuit CTO Award (Top 1% Performance), Intuit 2024
- • Intuit A2D Innovation Award (Top 1%, Team Lead), Intuit 2024, 2025
- • Promising Early-Career Researcher Award, Oak Ridge National Laboratory, US Department of Energy 2020
- • Chinese Outstanding Students Abroad Award, Ministry of Education of the P.R. China 2019
- • Acheson J. Duncan Graduate Research Award, Johns Hopkins University 2018
- • Dean's Fellowship, Johns Hopkins University 2014
- • China National Scholarship, Ministry of Education of the P.R. China 2009, 2012
Professional Services
- Area Chair: NeurIPS, ICLR, ACL, EMNLP, NAACL 2024–now
- Reviewer: NeurIPS, ICML, ICLR, ACL, EMNLP, NAACL, TMLR, JMLR, CVPR, ICCV, ECCV, AAAI, AISTATS, KDD 2020–now
Conference Travel
- • Jul 2026, ICML 2026 @ Seoul 🇰🇷
- • Apr 2026, ICLR 2026 @ Rio de Janeiro 🇧🇷
- • Dec 2025, NeurIPS 2025 @ San Diego 🇺🇸
- • Dec 2024, NeurIPS 2024 @ Vancouver 🇨🇦
- • Nov 2024, EMNLP 2024 @ Miami 🇺🇸
- • Jul 2024, ICML 2024 @ Vienna 🇦🇹
- • May 2024, AISTATS 2024 @ Valencia 🇪🇸
- • Jan 2024, WACV 2024 @ Hawaii 🇺🇸
- • Dec 2023, NeurIPS 2023 @ New Orleans 🇺🇸
- • Dec 2023, EMNLP 2023 @ Singapore 🇸🇬
- • Feb 2023, AAAI 2023 @ Washington, DC 🇺🇸
- • Dec 2022, NeurIPS 2022 @ New Orleans 🇺🇸
- • Jul 2022, ICML 2022 @ Baltimore 🇺🇸
- • Jun 2022, CVPR 2022 @ New Orleans 🇺🇸
- • Dec 2021, NeurIPS 2021 @ Online 🌐
- • Dec 2020, NeurIPS 2020 @ Online 🌐
- • Dec 2019, NeurIPS 2019 @ Vancouver 🇨🇦